Case study · MGSC 695
Transformer Topic Classifier
Fine-tuned RoBERTa vs a classic baseline
The question
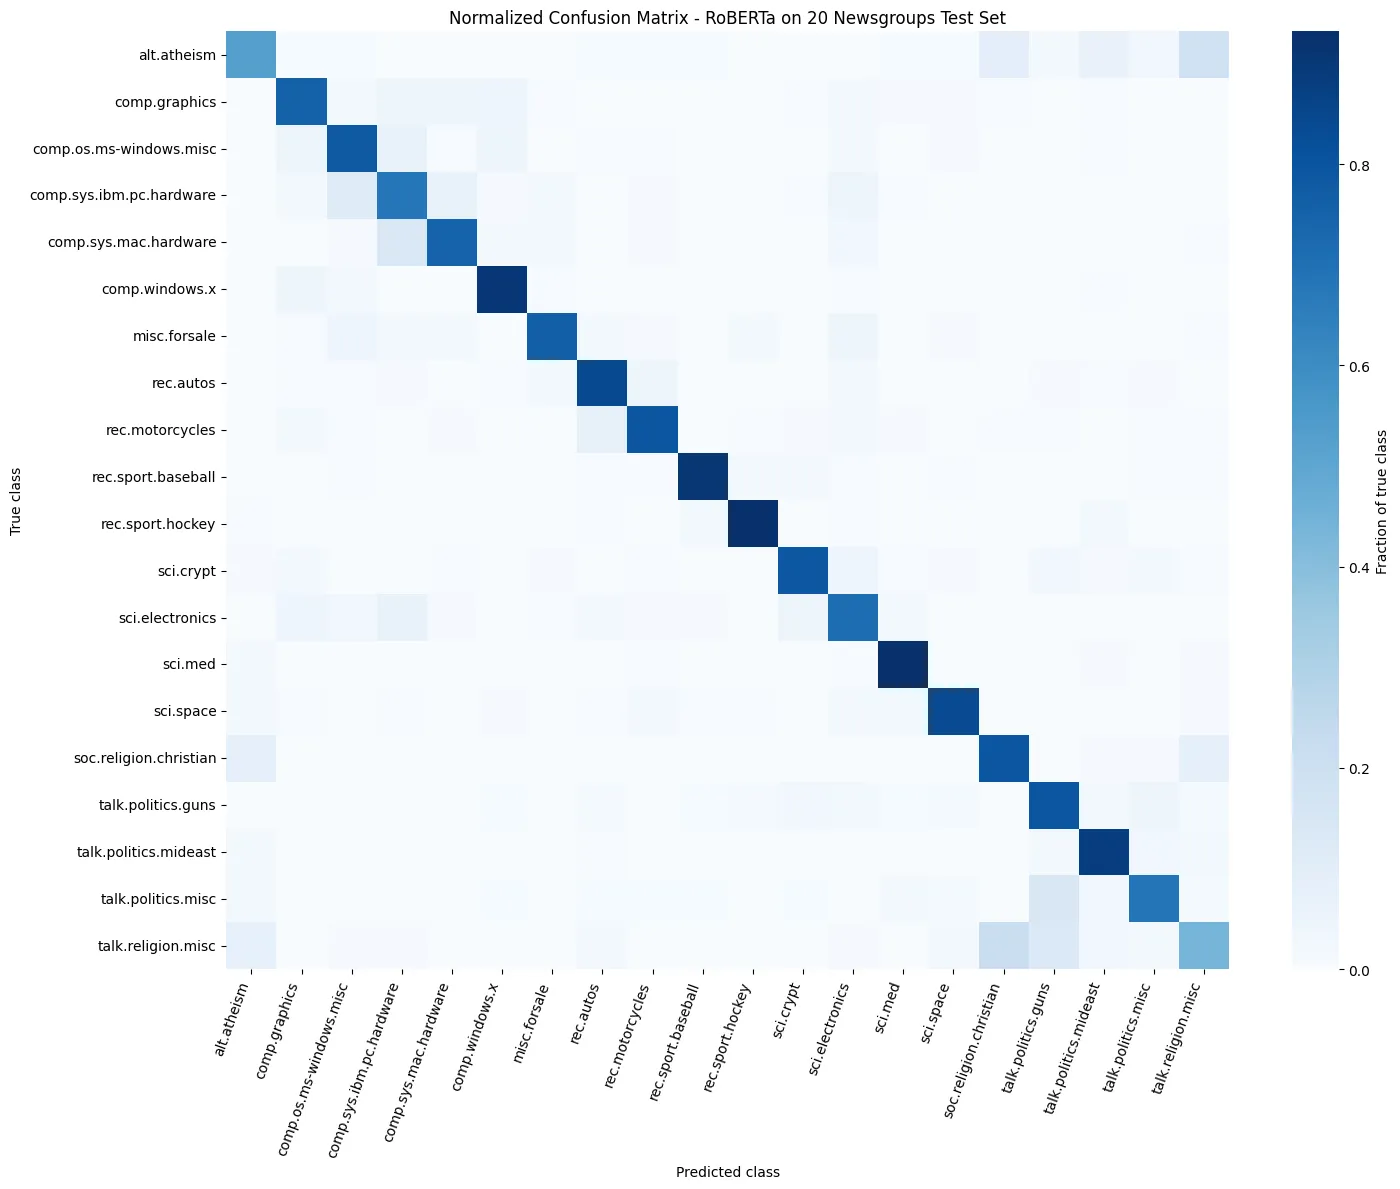
Twenty newsgroup topics that share vocabulary — religion, politics, computer hardware, recreation. How far does a fine-tuned transformer beat a classic baseline, and can its confidence be trusted?
Multi-class topic classification on 20 Newsgroups: RoBERTa fine-tuned and calibrated with temperature scaling, benchmarked against TF-IDF + logistic regression, then exported to ONNX with perfect prediction agreement.
How it works
- 01
Light cleaning, stratified train/validation/test splits, tokenization and training-only synonym augmentation.
- 02
Encoder and classification-head experiments, then full RoBERTa fine-tuning.
- 03
A TF-IDF + logistic regression baseline on the same held-out split.
- 04
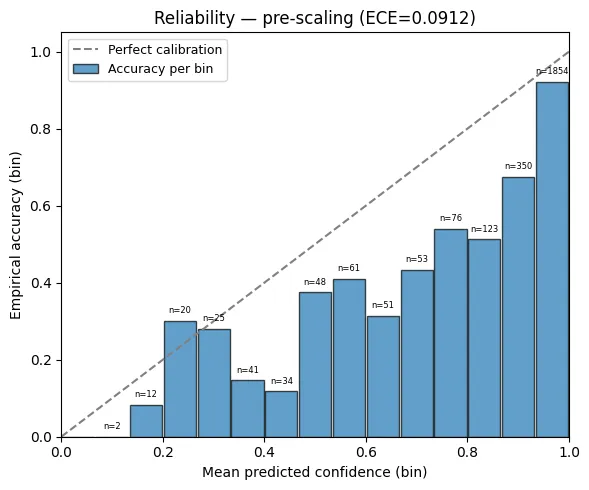
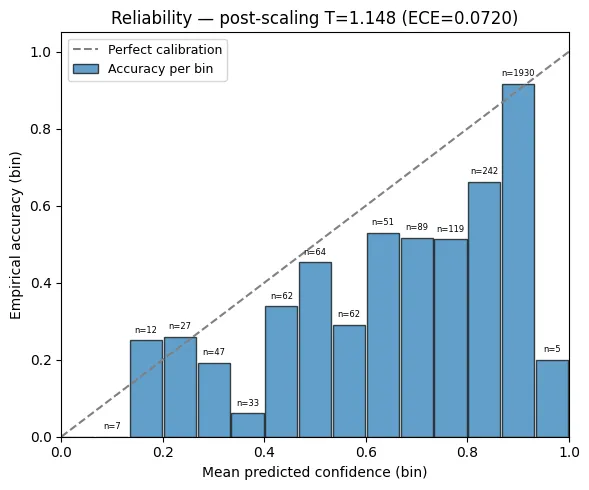
Class-level error analysis, attention diagnostics and local explanations; temperature scaling with reliability diagrams.
- 05
PyTorch → ONNX export checked for prediction agreement and latency, then cross-domain tests on AG News.
Results
77.60%
macro-F1 — vs 71.59% for TF-IDF
78.58%
held-out accuracy
0.0912 → 0.0720
calibration error after temperature scaling
1.000
PyTorch / ONNX prediction agreement
85.67%
AG News macro-F1, frozen encoder
Bottom line
ONNX is portable and prediction-equivalent — not faster. It measured 19.20 ms per example against 17.41 ms for PyTorch, so no speed-up is claimed.
From the repo
Known limits
- —20 Newsgroups is an older benchmark; it doesn't establish robustness on today's language or other domains.
- —Full GPU training wasn't rerun for the portfolio — the values come from the saved notebook outputs.